Local AI and Small Language Models
Specialize, Optimize, and Deploy Privately
Choose a model that suits your task, adapt it to your needs, and build software that runs locally. This free eBook features four chapters from four Manning books, covering small language models, specialization with LoRA and DoRA, CPU inference with GGUF and llama.cpp, and application development through Ollama’s Python library. Get practical guidance on producing structured outputs, making informed quantization choices, and handling streaming responses and chatbot conversation history. Get a firmer grasp of the choices behind local AI as well as concrete techniques to try in your next project, without depending on a hosted inference service.
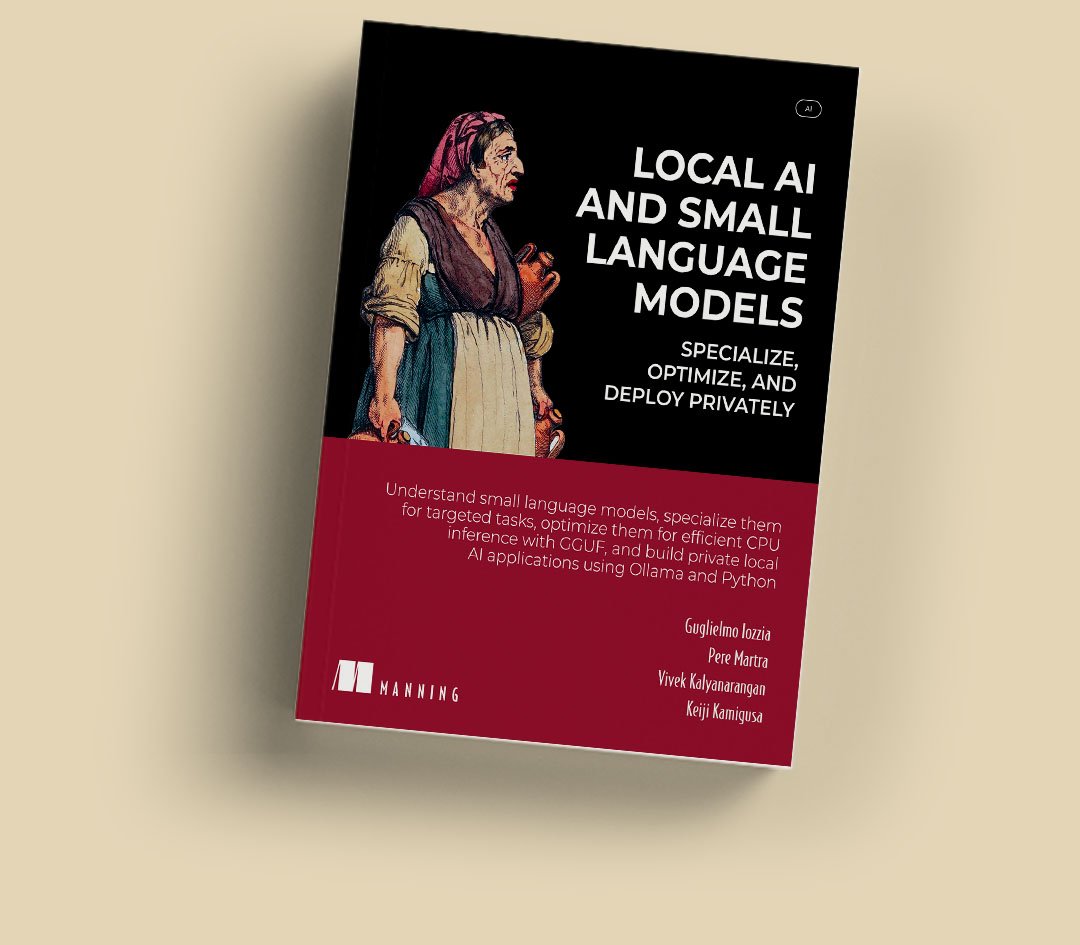
Download the Local AI and Small Language Models ebook for free!
Inside, you'll:
- Choose small models that fit your needs
- Adapt models for reliable, task-specific outputs
- Reduce model size with GGUF quantization
- Improve CPU inference performance
- Build local AI applications with Python and Ollama
- Create chatbots with streaming replies and conversation history
Get all 4 ebooks for $99.99 here!
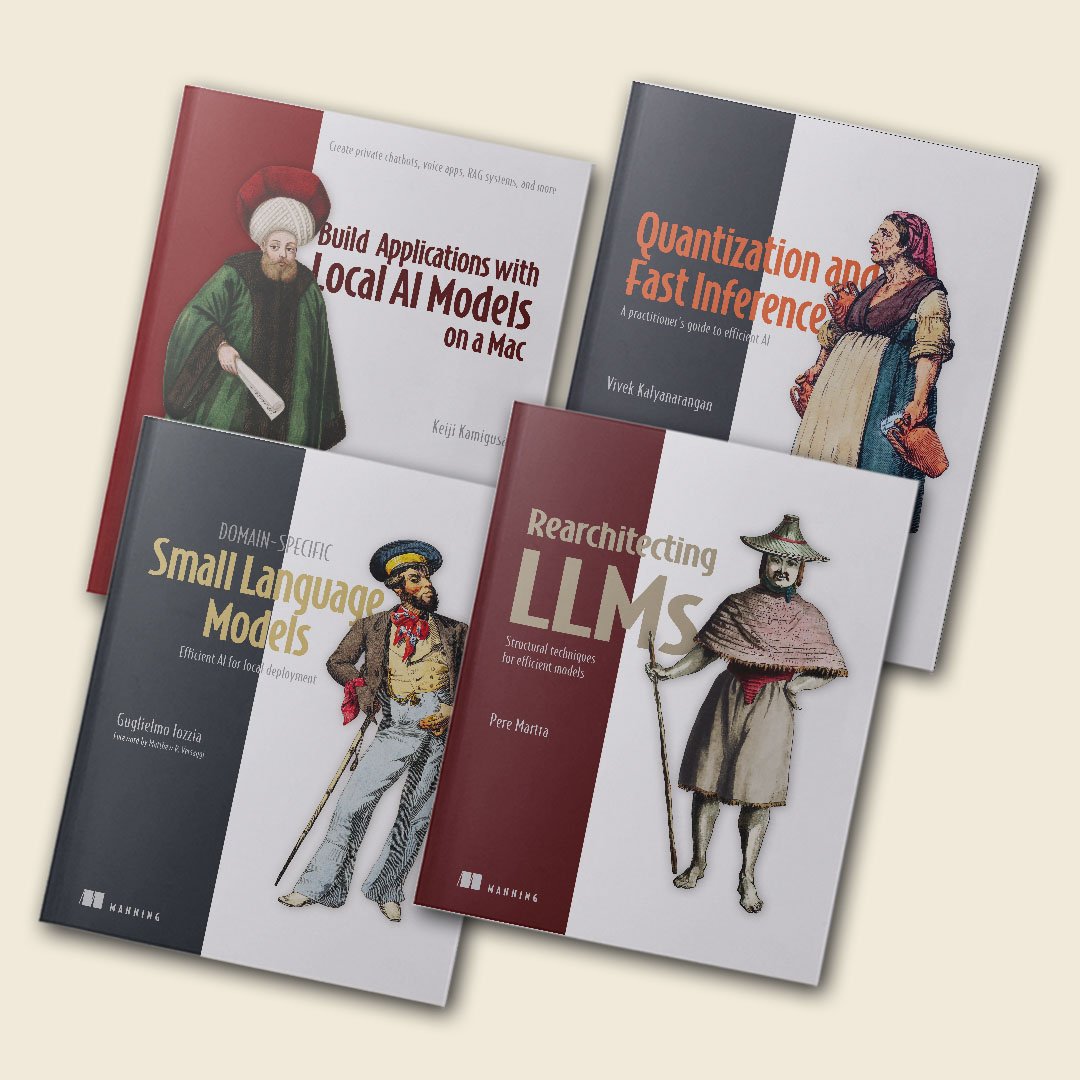
Domain-Specific Small Language Models
This is a practical book that shows you how to adapt pretrained open source models to your domain using transfer learning and parameter-efficient fine-tuning. You’ll learn to minimize cost through optimization and quantization, develop secure APIs to serve your models, and deploy SLMs on commodity hardware—including small devices. The hands-on examples include integrating SLMs into RAG systems and agentic workflows.
Build Applications with Local AI Models on a Mac
Running AI applications on local hardware unlocks architecturally guaranteed privacy, eliminates costly subscriptions and API fees, and gives you the power to tune your models to your exact needs. In Build Applications with Local AI Models on a Mac, author Keiji Kamigusa guides you step-by-step as you build a voice-enabled chatbot that will run on any recent Mac—from a basic Mac mini to a top-of-the-line Mac Studio. As you set up your custom hardware and software stack, you’ll experience a powerful paradigm shift that turns you from a passive consumer into an AI architect.
Quantization and Fast Inference
Today's AI models demand a lot of memory, compute, and server horsepower—which quickly translates into cost. Quantization and Fast Inference shows you how you can optimize AI models without architectural redesigns or task-specific compression. It reveals practical techniques for quantization, systematically reducing numerical precision to achieve faster inference, lower memory usage, and cheaper deployment—all with minimal accuracy loss.
Rearchitecting LLMs
Rearchitecting LLMs: Structural techniques for efficient models turns research from the latest AI papers into production-ready practices for domain-specific model optimization. As you work through this practical book, you’ll perform hands-on surgery on popular open-source models like Llama-3, Gemma, and Qwen to create cost-effective local small language models (SLMs). Along the way, you’ll learn how to combine behavioral analysis with structural modifications, identifying and removing parts that don’t contribute to your model’s goals, and even use “fair pruning” to reduce model bias at the neuron level.